Topic AI and LLMs

What Is RAG in AI? Explained for Business Owners, With Examples

The short answer

RAG (retrieval-augmented generation) lets an AI model answer from your own documents. When someone asks a question, the system first searches your documents for the passages that matter, then gives only those to the model and asks it to answer from them, citing where each part came from. The model is not retrained; your documents stay the source.

Written by

Siddharth Kajaria, Founder and CEO

Published

Reading time

14 min read

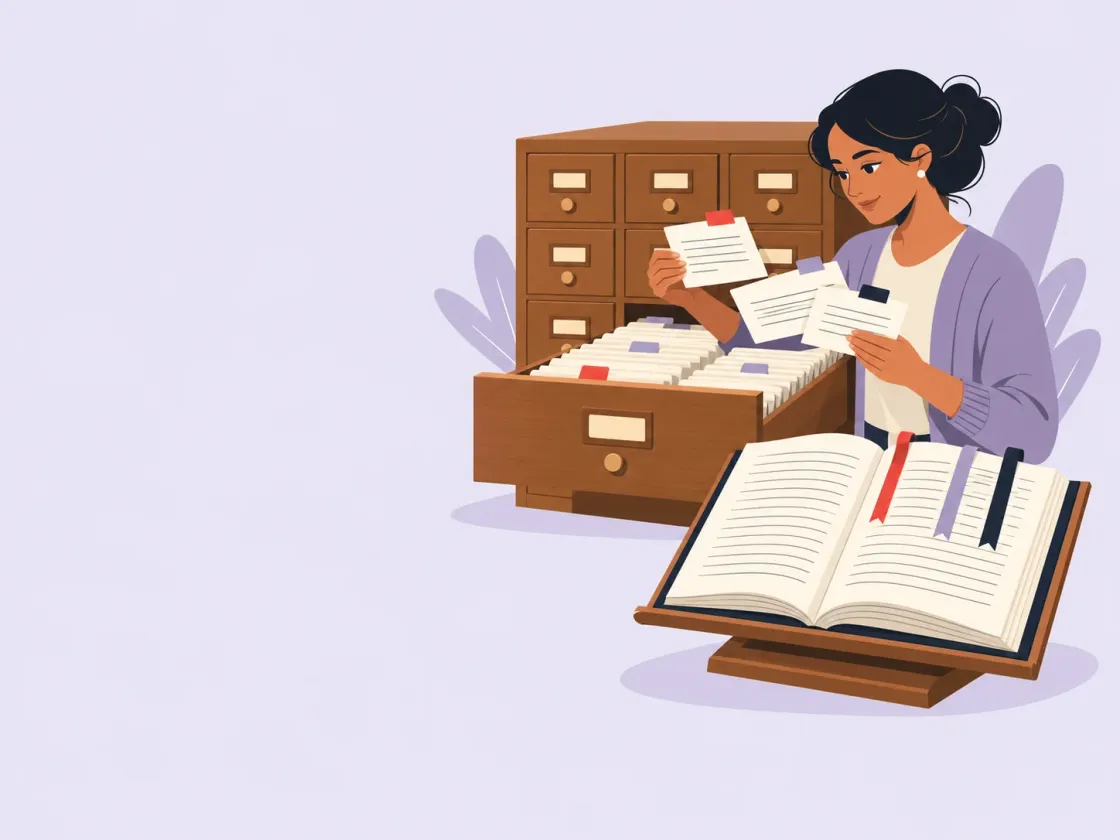
A woman pulls cards from a card catalogue, each pointing to a bookmarked passage in the open book in front of her.
In this post14 min read
  1. What is RAG in AI, in plain English?
  2. Can ChatGPT learn your company documents?
  3. Why do RAG answers still go wrong?
  4. What does RAG look like on a company policy library?
  5. Who can see what in a RAG system?
  6. Are your documents ready for RAG?
  7. What does a RAG system cost to run?
  8. When is RAG not the right tool?

Key takeaways

Teams that ask to “train ChatGPT on our documents” often want something else: an assistant that answers from their own policies, manuals or reports, gets the answer right, shows where it came from, and stays current when a document changes. Retraining a model is the wrong fix for that; RAG is the one that fits. Here it is without the jargon, compared with the alternatives, with the reasons it still goes wrong and a checklist for your documents.

What is RAG in AI, in plain English?

RAG, short for retrieval-augmented generation, is a way of making an AI model answer from a set of documents you choose, by finding the relevant passages first and handing them to the model with the question. The name comes from a 2020 research paper by Patrick Lewis and colleagues; the idea has since become a common way to build an assistant on a company’s own content.

Think of a library and a librarian. The model is a well-read librarian who has never seen your files. RAG gives the librarian a catalogue of your library. When a question arrives, the librarian looks it up in the catalogue, pulls the three or four pages that matter, reads them, and answers from them, with the page numbers.

In practice it runs in two stages:

  1. Prepare the library, once and then on every change. The system reads your documents, splits them into short passages, and stores them in a search index that can find passages by meaning, not only by exact words.
  2. Answer each question. It searches the index for the passages closest to the question, sends those passages and the question to the model, and instructs it to answer only from them and to say which passage each part came from.

The model itself is never changed. That is the point: your documents remain the source of truth, and when they change, the answers change with them.

Can ChatGPT learn your company documents?

Not by reading them once: a general chat model does not learn from your files, and retraining one on them is rarely the right way to get accurate answers. There are three real options, and they solve different problems.

  • RAG looks up your documents at the moment of each question.
  • Fine-tuning retrains a model on examples so that it behaves differently: a fixed format, a tone, a classification task. Our advice: fine-tuning changes how a model behaves, not what it knows, so it is the wrong tool for facts that change. OpenAI’s guide lists uses such as classification, a set output format and fixing instruction-following. OpenAI is also winding down its fine-tuning platform, which is no longer open to new users.
  • Long context means pasting the documents straight into the conversation. Current models can read a lot of text at once, so for a small, stable set of documents this can be enough.
RAG, fine-tuning and long context compared for answering from your own documents
Compared onRAGLooks up your documents per questionFine-tuningRetrains the model on examplesLong contextPastes the documents into the chat
What it changesWhat the model reads before it answersHow the model behaves: format, tone, a narrow taskWhat the model reads, all of it, every time
When a document changesRe-index it; the next answer uses the new textRetrain, or the old facts stay in the modelPaste the new version next time
Shows its sourcesYes, passage by passage, if built toNo: the facts are mixed into the modelIt can quote, but finding the spot in a long text is less reliable
Size of library it suitsSmall to very largeNot a way to store a libraryA few documents that fit in one request
Who sees whatCan filter by each user’s permissions before the searchWhatever went into training can come out for anyoneWhoever has the chat sees everything pasted in
Running costA short set of passages per questionTraining up front, then normal usageThe whole text is read on every question
How it failsFinds the wrong passage, or an old versionStates outdated or blended facts with confidenceMisses a detail buried in the middle of a long text
Best whenPeople need current answers from many documents, with sources, and not everyone may see everythingYou need a consistent format, tone or classification, and the facts come from somewhere elseThe documents are few, short and stable, and everyone may read all of them

These options combine. A support assistant can use RAG for the facts and a carefully written set of instructions for the tone. A team with a single 30-page handbook may never need RAG at all, until the handbook becomes forty documents owned by six departments.

Why do RAG answers still go wrong?

RAG answers go wrong for three reasons: the documents are wrong, the search picked the wrong passages, or the model used the right passages badly. The model gets the blame, so check the documents and the search first: those are the cheapest places to fix.

9 common causes

Generic failure patterns, not client projects

The documents

  1. Old versions sit beside new ones

    The fix
    One current version per policy in the index, and old ones removed, not just renamed “OLD”.
    How you spot it
    Answers quote rules people say changed long ago. The cited document’s date gives it away.
  2. Scanned PDFs with no text

    The fix
    Text extraction for scans, checked by a person for tables and small print, or the original files.
    How you spot it
    Whole documents never appear in any answer, as if they didn’t exist.
  3. The answer isn’t written down

    The fix
    Write it down, in the document where people would look for it.
    How you spot it
    The assistant says “I don’t know”, which is correct, or worse, stitches together a guess.

The search

  1. Passages cut in the wrong place

    The fix
    Split documents along their own headings and keep tables whole, with the section title attached to each passage.
    How you spot it
    Answers that are right but incomplete: the rule without its “except when”.
  2. Words that don’t match

    The fix
    Combine meaning-based search with plain keyword search, and keep a short glossary of internal terms.
    How you spot it
    Questions phrased the way staff speak get worse answers than questions phrased like the policy.
  3. Too many passages, or too few

    The fix
    Tune how many passages are sent, and re-rank them so the best few go first.
    How you spot it
    Answers swing between thin and rambling for similar questions.

The answer

  1. No citations

    The fix
    A source link with every answer, pointing to the passage, and its document date.
    How you spot it
    Users stop trusting it after the first wrong answer they catch, and can’t tell right from wrong after that.
  2. It guesses instead of saying “I don’t know”

    The fix
    Instructions to answer only from the passages, and a clear “not covered” reply that is logged for the content team.
    How you spot it
    Confident answers on topics your documents never mention.
  3. Nobody tests it after a change

    The fix
    A fixed set of real questions with known answers and sources, re-run after every change.
    How you spot it
    Complaints arrive weeks after the change, and nobody knows which change caused them.

Citations and an honest “I don’t know” are the two features that make the rest of these failures visible. The NFTR Assistant we built answers from its knowledge base, cites its sources and reports unanswered questions to admins, so the team can see which content is missing and add it. It sits inside the NITI Aayog Frontier Tech Repository portal, which we built. Every unanswered question becomes a to-do item for the content team, rather than a guess shown to a user.

Have documents in mind?

What does RAG look like on a company policy library?

A worked example shows the difference best. Take a 400-person company with an HR and operations policy library, and follow the same four staff questions through three set-ups: a general chat model, the handbook pasted into a long-context model, and a RAG assistant with citations.

Worked example

Illustrative example, not a client project

The set-up

The company
About 400 staff across three offices
The library
60 HR, travel, IT and finance policies; some are scanned, two exist in an old and a new version
The goal
Staff get correct answers at any hour, and HR gets fewer repeat questions
Four staff questions on a policy library under a general chat model, long context and RAG
QuestionWhat was askedGeneral chat modelNo access to the policiesLong contextThe handbook pasted inRAG with citationsSearches all 60 policies
Q1“How many days of paternity leave do I get?”A general answer about typical leave, with no way to know your company’s rule.Correct, because the leave policy is in the handbook that was pasted in.Correct, with a link to the leave policy and its date.
Q2“Can I claim a taxi to the airport?”A guess.Wrong: the travel policy is a separate document that wasn’t pasted in.At first it quotes the old travel policy. After the old version is removed from the index, correct, with the source.
Q3“What’s the expense limit for client dinners in Mumbai?”A guess, stated confidently.Not in the handbook, so the model either says so or guesses.The limit table is in a scanned PDF. Nothing is found until the scan’s text is extracted; then correct, with the table cited.
Q4“What did the board decide about bonuses?”A guess.If the board minutes were pasted in, anyone using the chat can read them.The minutes are restricted, so the search skips them for this user and the answer says the question isn’t covered.
Where it endedFine for general writing help, wrong for company rules.Good for the one document pasted in, blind to the rest, with no permissions.Right on all four, once two document problems were fixed. The fixes were in the library, not the model.

What the example shows

Who can see what in a RAG system?

A RAG assistant can show a user any passage in its index, so it must check what each user is allowed to see before it searches, not after it answers. If the board minutes and the salary bands are in the index and the search ignores permissions, an intern’s question can surface them.

  • Carry the permissions over. Each passage keeps the access rules of the document it came from, and the search only looks in passages the person asking may open.
  • Separate indexes for separate audiences. A public website assistant and a staff assistant should not share one index, even where much of the content overlaps.
  • Keep what should never be searched out of the index. Personal data, contracts under negotiation and legal advice are easier to protect by leaving them out than by filtering them later.
  • Log the questions and the passages used, and decide who can read those logs: questions people ask often contain sensitive details themselves.

How these rules are set up for a given client depends on where their documents live and who needs access.

Are your documents ready for RAG?

Your documents are ready for RAG when each answer exists in one current, readable place, with an owner who keeps it up to date. Check your library against the tests below before you build anything: the score tells you whether to start building or start tidying.

Document readiness checklist

The content

Show or hide the tests4 tests
  1. 01 One current version of each document

    True when
    Why it matters
  2. 02 The text can be selected and copied

    True when
    Why it matters
  3. 03 The answers people need are written down

    True when
    Why it matters
  4. 04 Documents have headings and dates

    True when
    Why it matters

Read next AI chatbot development

The upkeep

Show or hide the tests4 tests
  1. 05 Each document has an owner

    True when
    Why it matters
  2. 06 The documents live in one place, or a few

    True when
    Why it matters
  3. 07 You know who may see what

    True when
    Why it matters
  4. 08 You can list 50 real questions with their right answers

    True when
    Why it matters

Read next AI and LLMs

A low score is not a reason to give up. It is a list of the first month’s work, and the tidying pays off for the people who read the documents, too.

What does a RAG system cost to run?

A RAG system’s running cost comes mainly from model usage, which grows with the number of questions, the amount of text sent with each one and the model you choose, plus the search index and the time people spend keeping the documents current. Per question, it calls the model once per answer, where an AI agent calls it at every step of a loop, so plan for a lower cost per question than an agent.

What makes a RAG system cost more to run, and what to ask for instead
What drives itWhy it costs moreWhat to ask for
Number of questionsEach question calls the model once, so cost grows with use.An estimate per answer, multiplied by your expected monthly volume, and what happens if it doubles.
Passages sent per questionModels charge by the amount of text they read. Ten long passages cost several times three short ones.Fewer, better-ranked passages, and tests that show the answers didn’t get worse.
The model chosenThe largest models cost much more per answer, and many questions don’t need them.A smaller model for routine questions, tested on your real question set before you decide.
Repeated questionsThe same twenty questions asked a thousand times are answered from scratch a thousand times.Caching for common questions, where the provider and the set-up support it.
The search indexThe index that stores your passages has its own hosting cost, and re-reading a large library on every change takes compute.Re-index only the documents that changed, and size the index for the library you have.
Keeping documents currentPeople’s time fixing gaps and old versions is a running cost, and the easiest one to leave out of the estimate.A named owner per area and a monthly look at the unanswered-questions log.

Measure before you commit: run the assistant on a few hundred real questions, record the cost per answer, and multiply by the volume you expect. For what building one involves, see AI chatbot development, and for the wider build and running costs, the AI app development cost guide.

When is RAG not the right tool?

RAG is the wrong tool when the job is to do something rather than to answer something. If the assistant needs to file a ticket, update a record or chase a supplier, it needs to act through tools, which makes it an agent, with all the guardrails that brings: see what an AI agent is. RAG is also overkill for a handful of short documents that rarely change, where long context does the job, and it cannot fix a task that needs a different skill, such as reading handwriting or calculating a figure, which belongs in code. For the models and integrations behind all three, see our page on AI and LLMs.

02 FAQ

Questions, answered

Does RAG stop an AI model from making things up?
It reduces it a lot, but it does not remove it. The model can still misread a passage, combine two passages wrongly or fill a gap with a guess. Three habits keep this in check: instruct it to answer only from the passages it was given, show the sources with every answer so people can check, and test it on real questions with known answers before and after every change.
Is our data sent to the AI provider when we use RAG?
The passages picked for each question are sent to the model with the question, so yes, that text reaches whichever model you use. Your full library does not, unless you send it. Check the provider's data terms for the plan you use, ask whether prompts are stored or used for training, and ask whether the model can run in a cloud region or account you control.
What happens when our documents change?
The system re-reads the changed documents and updates its search index, so the next answer uses the new text. How quickly that happens depends on how it is set up: some systems sync on a schedule, others when a file is saved. Ask for the sync interval, and for old versions to be removed from the index rather than kept beside the new ones.
Can a RAG chatbot work in Hindi or other Indian languages?
It can, if the model you choose handles those languages well: check the provider's list of supported languages first. The quality depends on the model, on the language your documents are written in, and on whether the search step handles questions in one language and documents in another. Test it with real questions in each language your users will ask in before you launch.